What is Qwen?
Qwen represents the robust series of large language and multimodal models developed by the Qwen Team at Alibaba Group. Designed for advanced natural language processing (NLP) and multimodal interactions, Qwen supports tasks across natural language understanding, text generation, visual and audio comprehension, and more.
What is Qwen 2.5 Coder ?
Qwen2.5-Coder is the latest series of Code-Specific Qwen large language models (formerly known as CodeQwen).Qwen2.5-Coder, is specifically designed for coding applications. Qwen2.5-Coder-32B has now emerged as the leading open-source code LLM, with coding capabilities comparable to GPT-4o.
Features
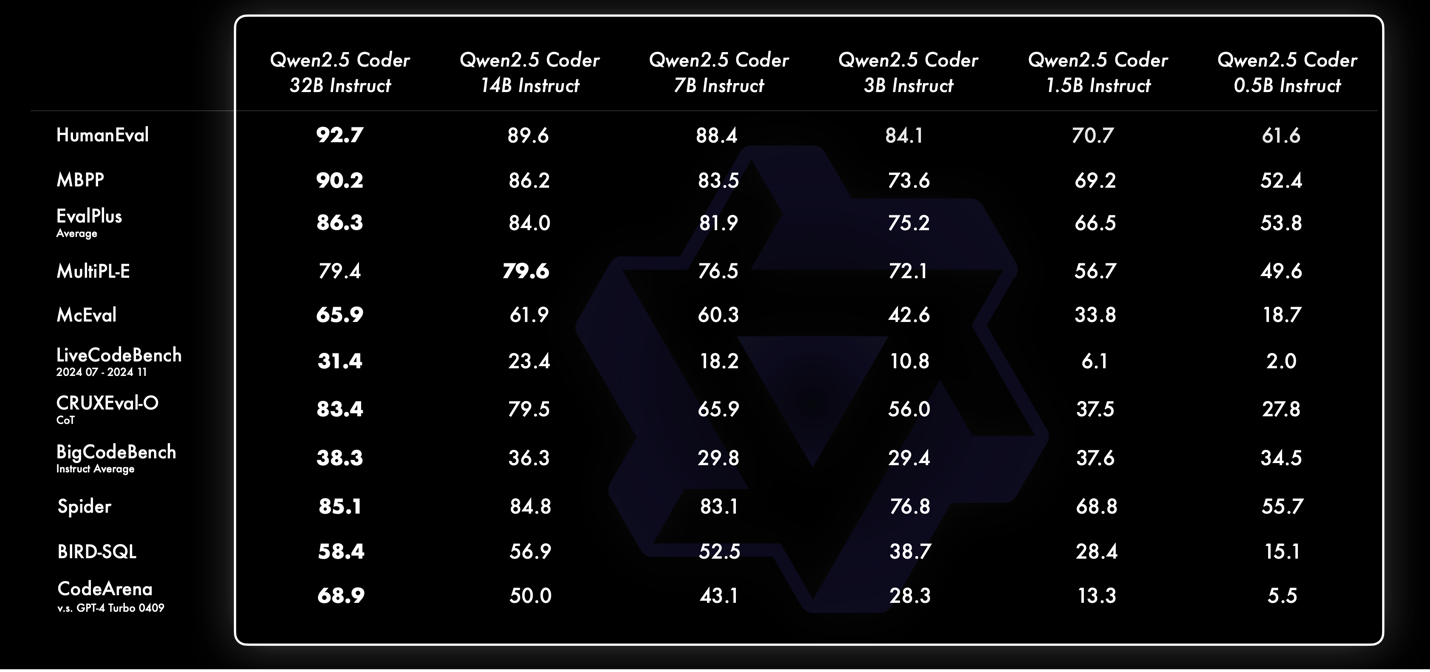
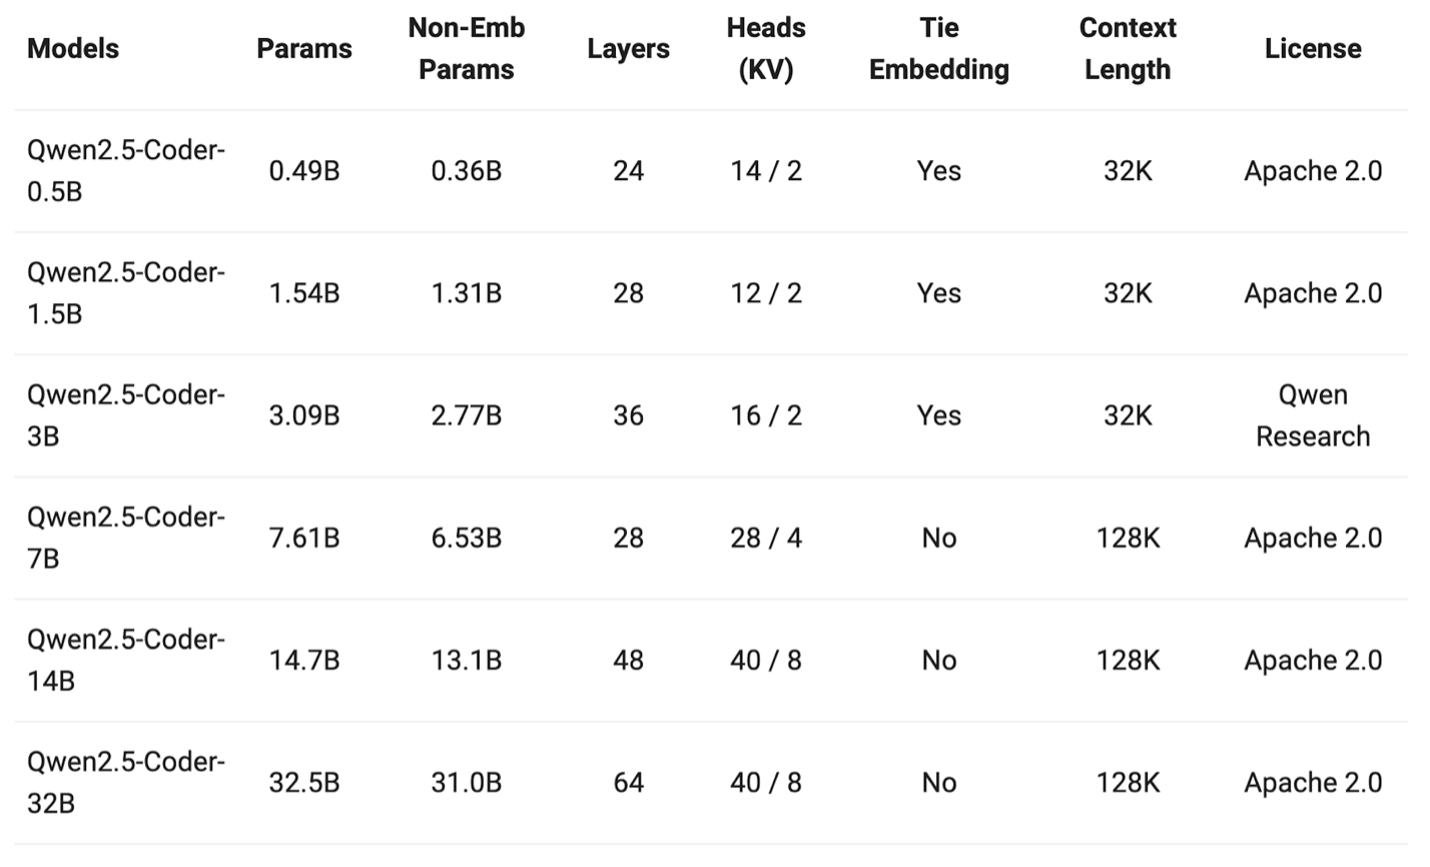
Model Variants: The QWEN2.5 Coder series includes models with 0.5B, 1.5B, 3B, 7B, 14B, and a forthcoming 32B parameters. The focus here is primarily on the 7B variant, which has been instruction-tuned for enhanced performance in coding tasks.
Training Data: The models have been pretrained on an extensive dataset comprising over 5.5 trillion tokens. This dataset includes a diverse source code, text-code grounding data, and synthetic data generated to improve model robustness and versatility.
Architecture: QWEN2.5 Coder employs a transformer architecture enhanced with several advanced techniques:
Enhanced Features in Qwen 2.5
Extended Context Length:
Supports a context length of up to 128,000 tokens, allowing for comprehensive understanding and generation of long-form content.
Ideal for applications in document analysis, legal processing, and multi-turn conversational tasks, where continuity and depth are critical.
Support for 92 Coding Languages:
Equipped with capabilities across 92 programming languages, including major languages like Python, JavaScript, and C++, as well as niche languages.
This versatility meets the needs of a broad range of developers, from software engineering to specialized scientific computing.
Retained Strengths in Math and General Capabilities:
Maintains robust mathematical reasoning and general cognitive capabilities from the base model, ensuring high performance across diverse tasks.
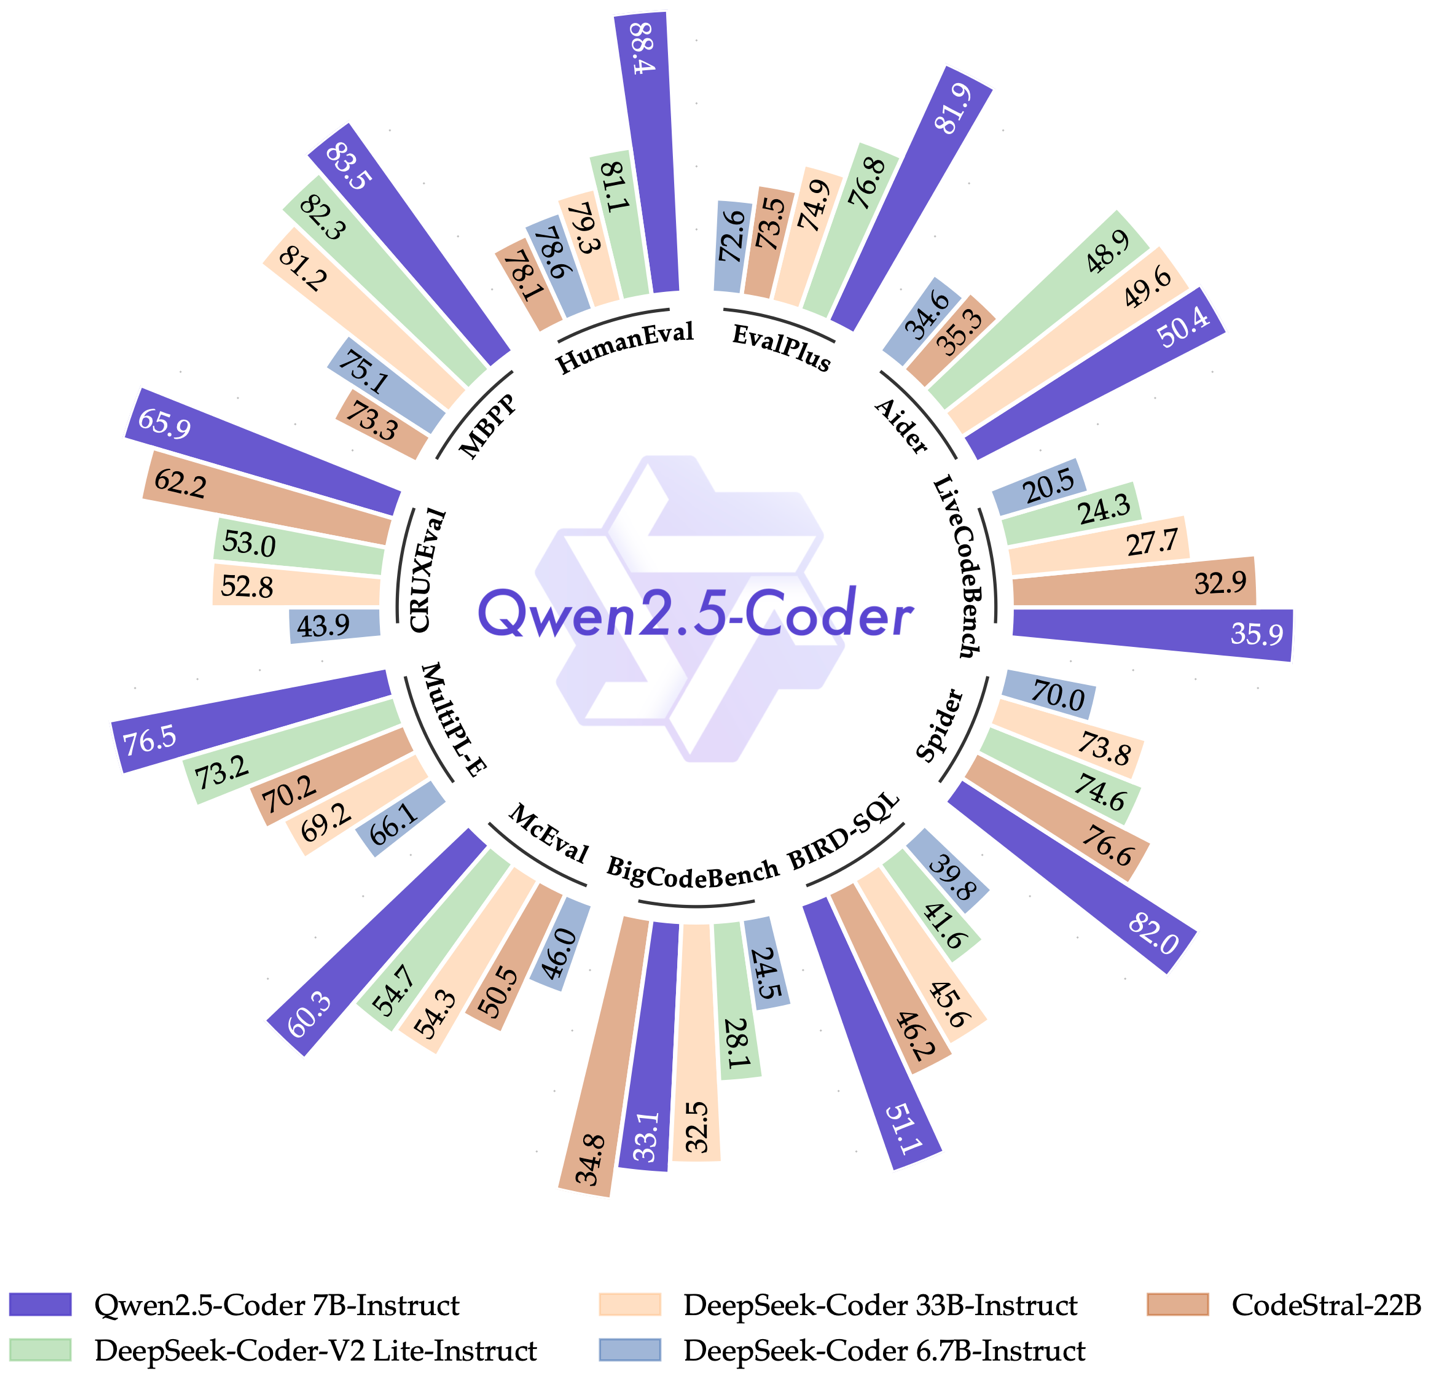
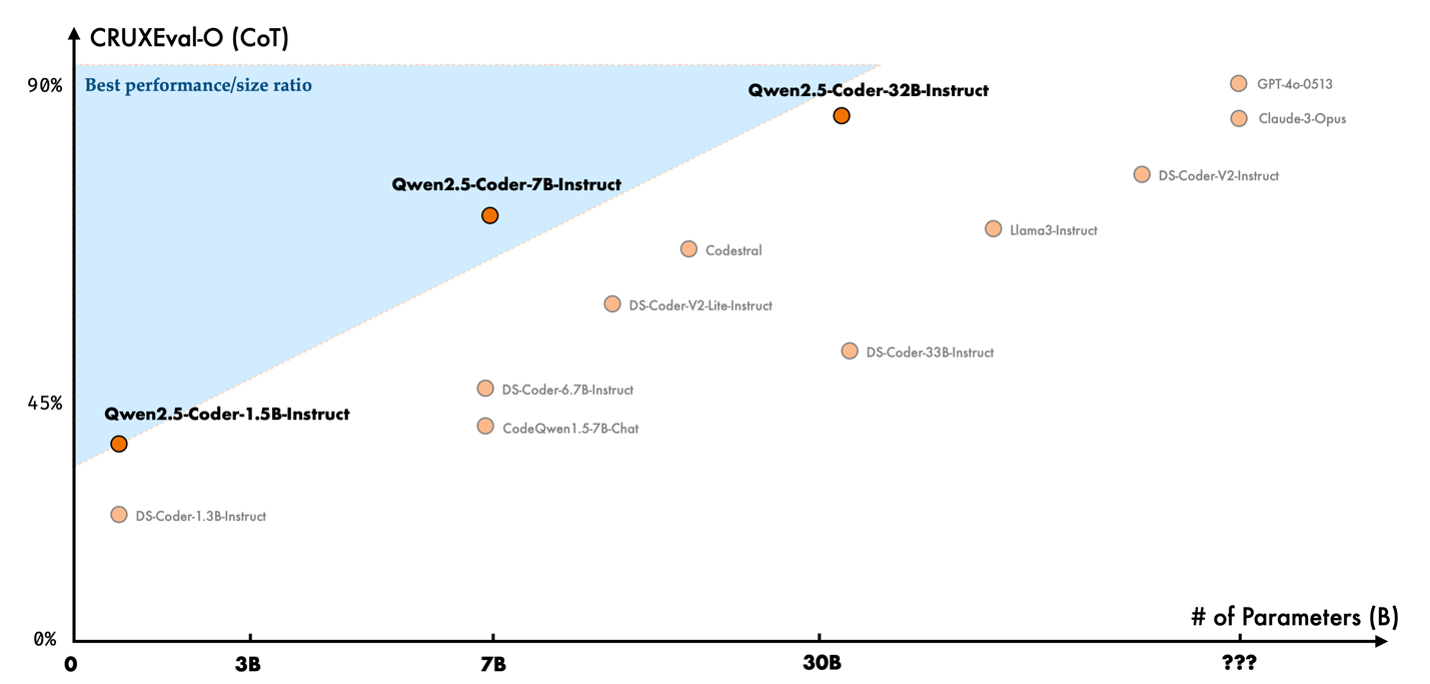
Below presents the performance results of Qwen2.5-Coder-7B-Instruct, benchmarked against leading open-source models, including those with significantly larger parameter sizes.
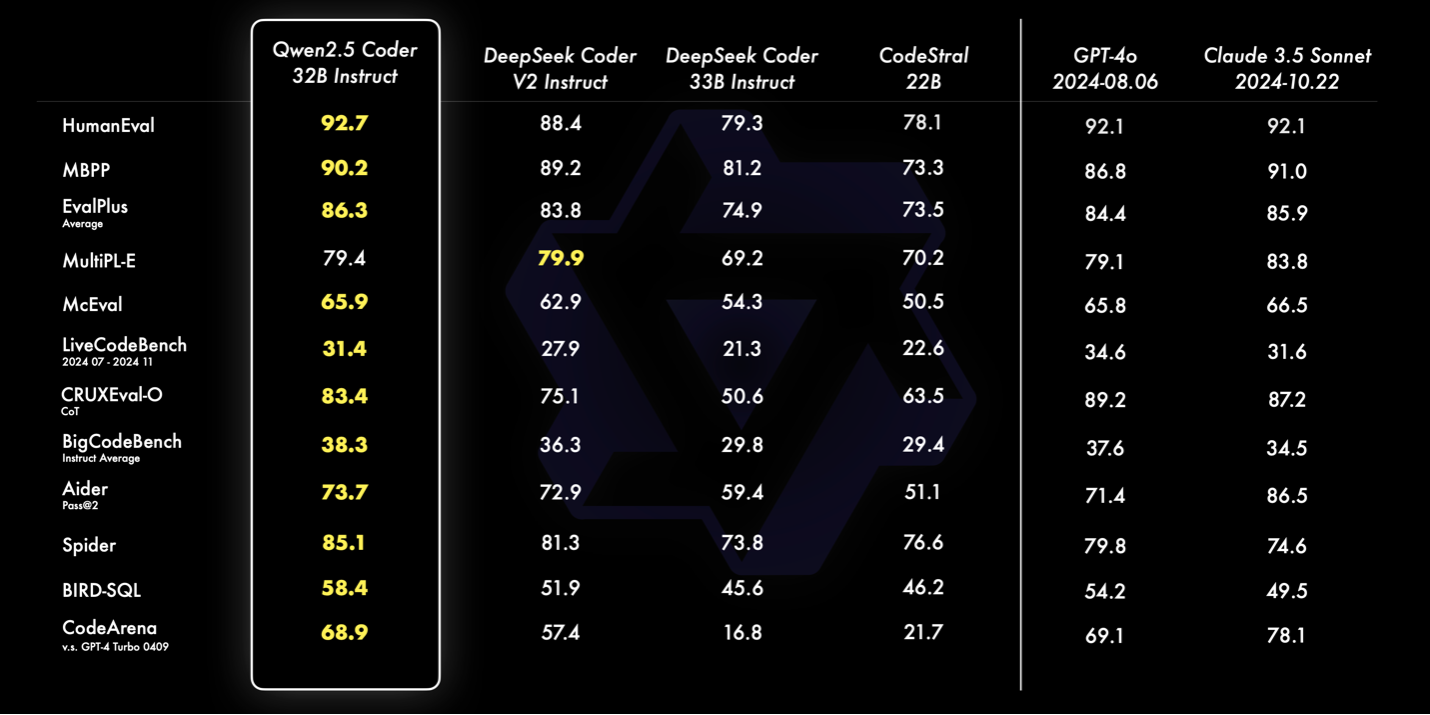
Unmatched Performance: Achieving State-of-the-Art Coding Capabilities in Open-Source Models
Code Generation: Qwen2.5 Coder 32B Instruct, as the flagship model of this open-source release, has achieved the best performance among open-source models on multiple popular code generation benchmarks (EvalPlus, LiveCodeBench, BigCodeBench), and has competitive performance with GPT-4o.
Code Repair: Code repair is an important programming skill. Qwen2.5 Coder 32B Instruct can help users fix errors in their code, making programming more efficient. Aider is a popular benchmark for code repair, and Qwen2.5 Coder 32B Instruct scored 73.7, performing comparably to GPT-4o on Aider.
Code Reasoning: Code reasoning refers to the model’s ability to learn the process of code execution and accurately predict the model’s inputs and outputs. The recently released Qwen2.5 Coder 7B Instruct has already shown impressive performance in code reasoning, and this 32B model takes it a step further.
Multiple programming languages
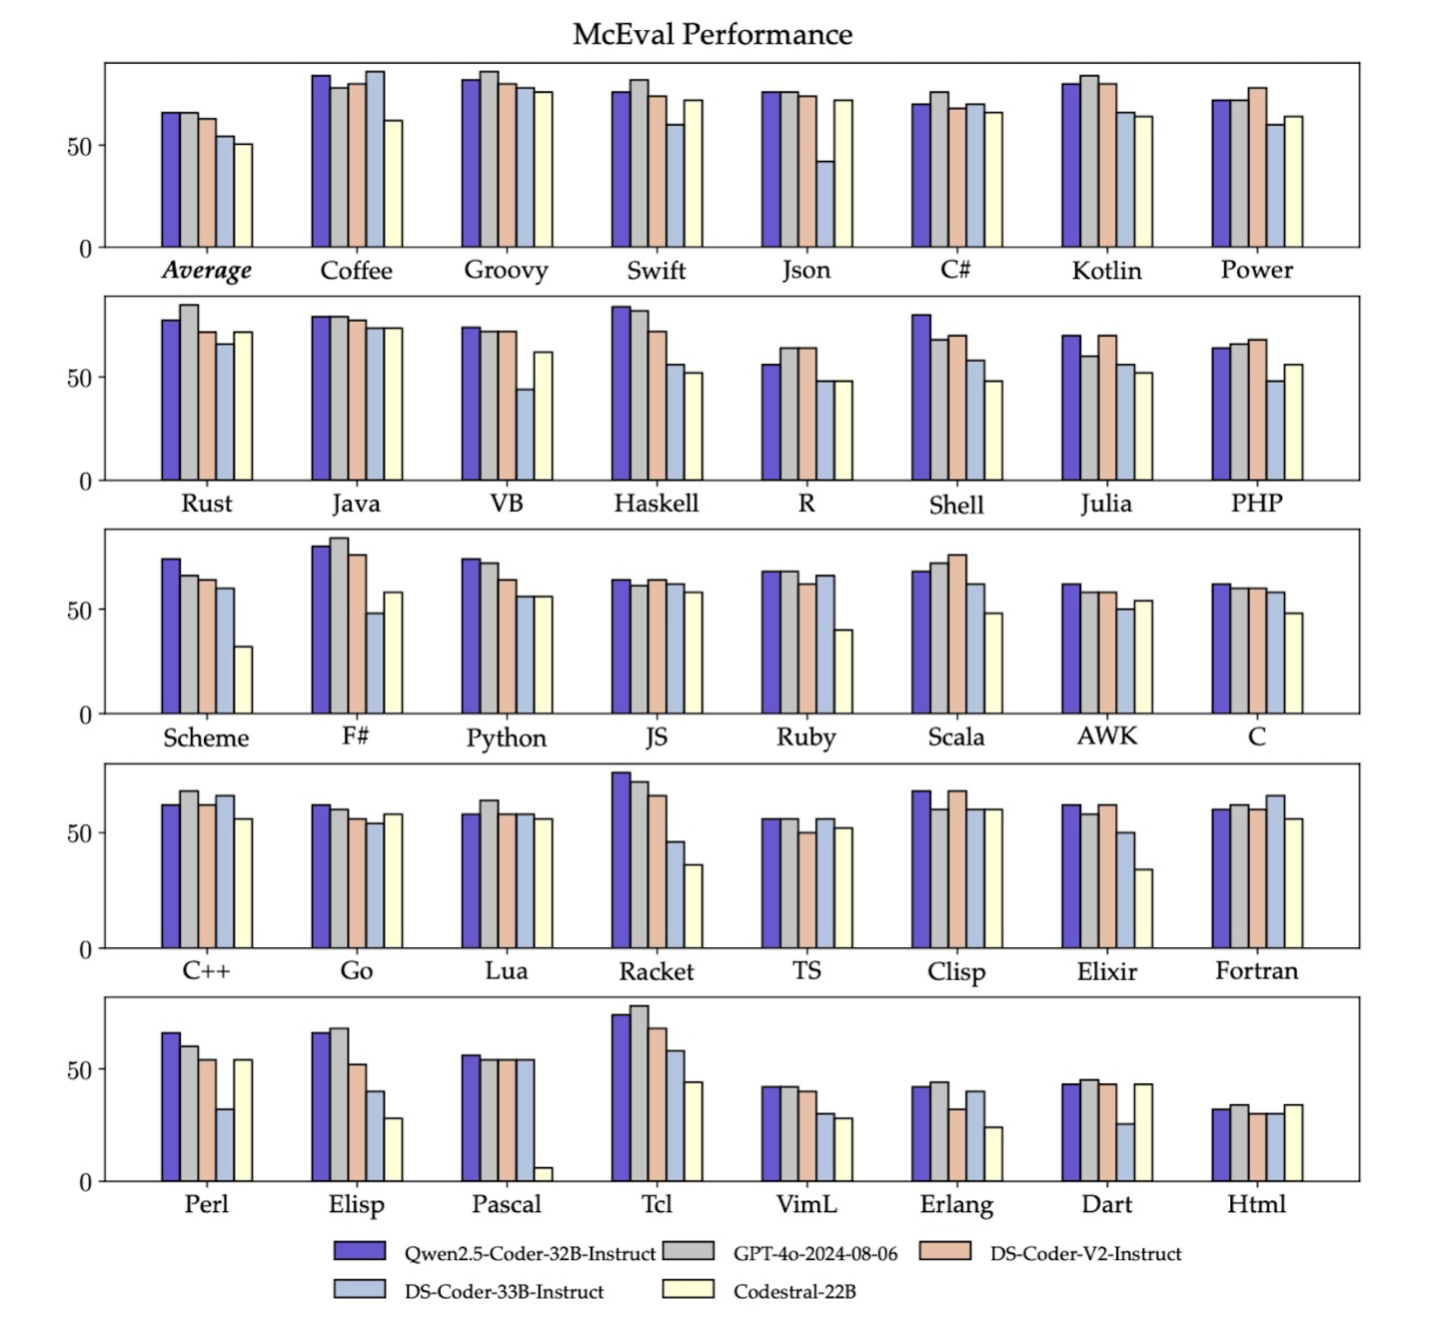
An intelligent programming assistant should have proficiency across all programming languages. Qwen 2.5 Coder 32B excels in over 40 languages, achieving a score of 65.9 on McEval, with standout performance in languages like Haskell and Racket. The Qwen team applied their own specialized data cleaning and balancing techniques during the pre-training phase to achieve these results.
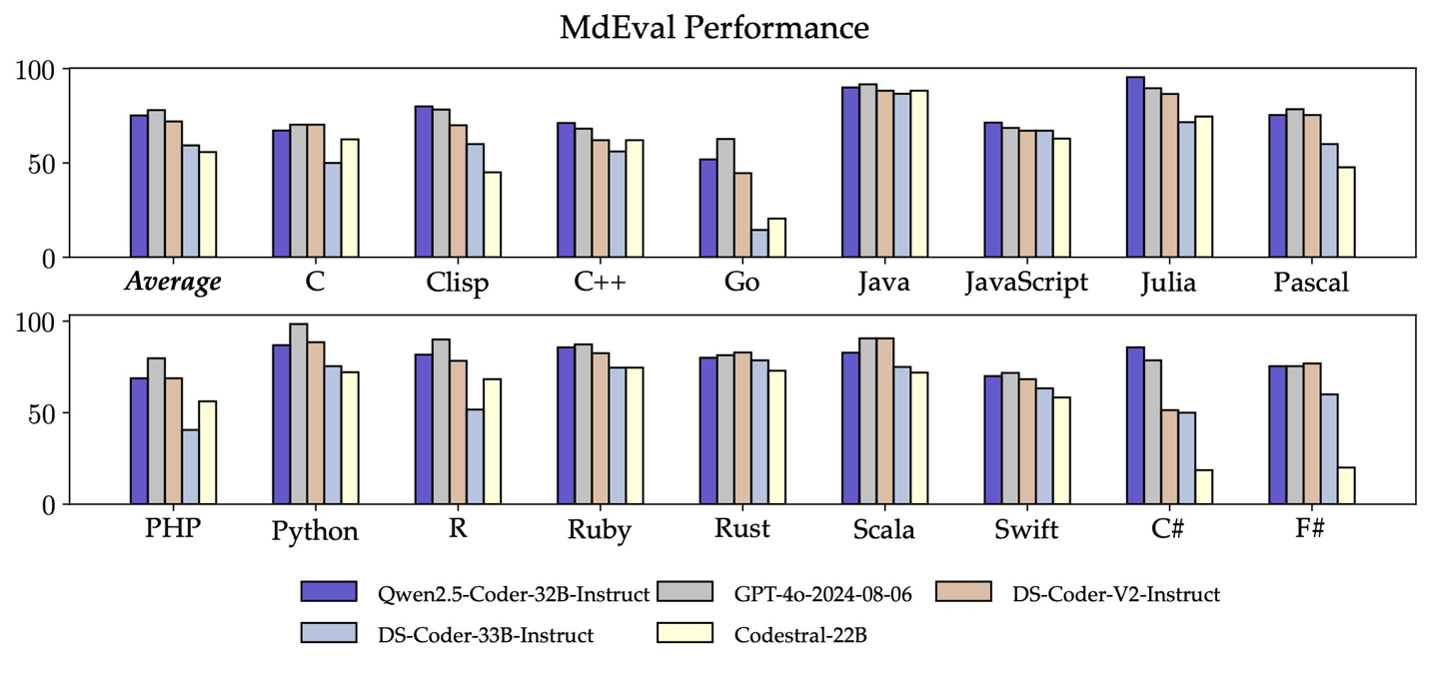
Additionally, the multi-language code repair capabilities of Qwen 2.5 Coder 32B Instruct remain impressive, aiding users in understanding and modifying programming languages they are familiar with, significantly reducing the learning cost of unfamiliar languages. Similar to McEval, MdEval is a multi-language code repair benchmark, where Qwen 2.5 Coder 32B Instruct scored 75.2, ranking first among all open-source models.
Human Preference Alignment
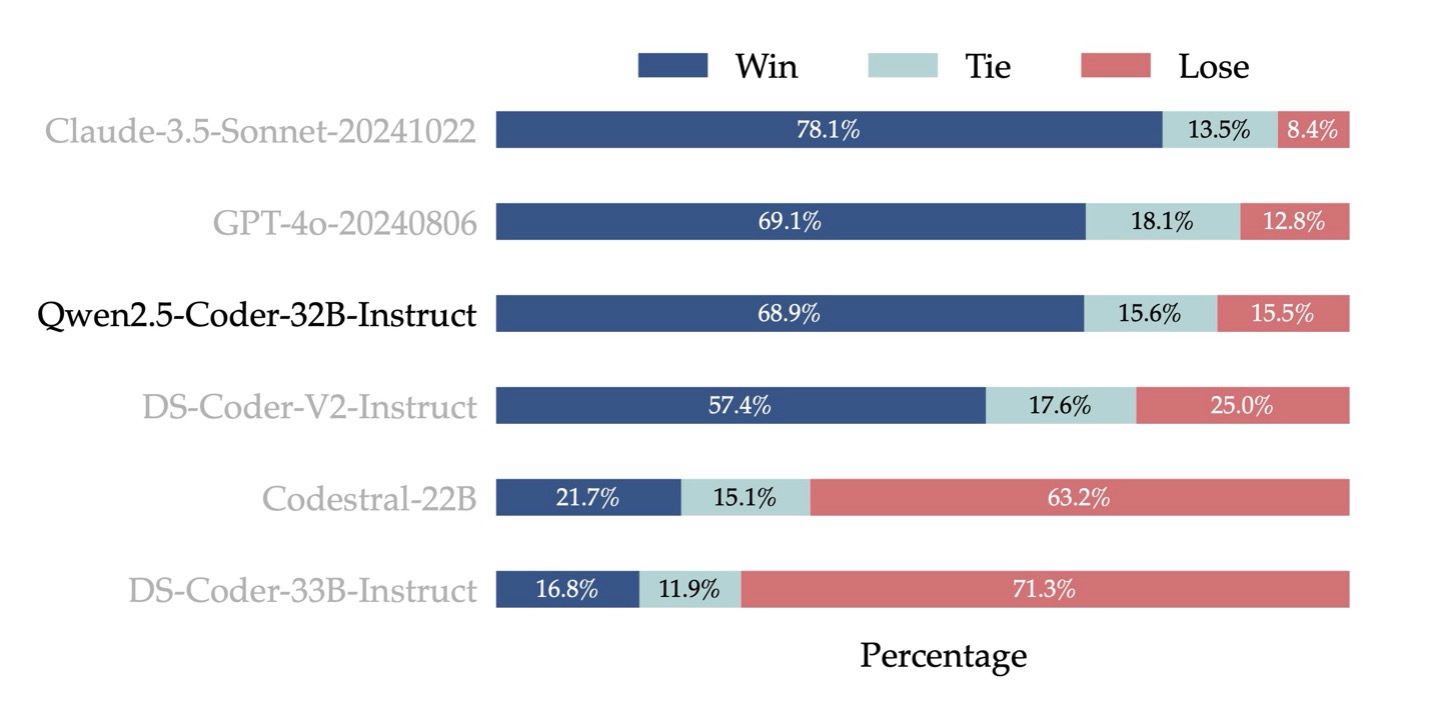
To evaluate the alignment performance of Qwen2.5-Coder-32B-Instruct with human preferences, we constructed an internal annotated code preference evaluation benchmark called Code Arena (similar to Arena Hard). We used GPT-4o as the evaluation model for preference alignment, employing an ‘A vs. B win’ evaluation method, which measures the percentage of instances in the test set where model A’s score exceeds model B’s. The results below demonstrate the advantages of Qwen2.5-Coder-32B-Instruct in preference alignment.
A range of model sizes tailored to fit your device
References
https://qwenlm.github.io/blog/qwen2.5-coder-family/
https://huggingface.co/collections/Qwen/qwen25-coder-66eaa22e6f99801bf65b0c2f